TalkRL: The Reinforcement Learning Podcast
TalkRL is a podcast dedicated to reinforcement learning, featuring in-depth interviews with researchers and practitioners at the forefront of the field. Guests come from major institutions and labs such as MILA, OpenAI, MIT, DeepMind, Berkeley, Amii, Oxford, Google Research, Brown, Waymo, Caltech, and the Vector Institute. The show explores both fundamental ideas and practical applications in RL. It is hosted by Robin Ranjit Singh Chauhan.
Episodes
Thomas Frost on Clinical RL with Natural Timings
Dr Thomas Frost is an emergency physician based in London, UK. He is also in the final stages of completing a PhD at University College London, where he has been looking at offline reinforcement learning applied to healthcare settings.Featured ReferencesRobust Real-Time Mortality Prediction in the Intensive Care Unit using Temporal Difference Learning Thomas Frost, Kezhi Li, Steve Harris
Danijar Hafner on Dreamer v4
Danijar Hafner was a Research Scientist at Google DeepMind until recently.Featured References Training Agents Inside of Scalable World Models [ blog ] Danijar Hafner, Wilson Yan, Timothy LillicrapOne Step Diffusion via Shortcut ModelsKevin Frans, Danijar Hafner, Sergey Levine, Pieter AbbeelAction and Perception as Divergence Minimization [ blog ] Danijar Hafner, Pedro A. Ortega, Jimmy
David Abel on the Science of Agency @ RLDM 2025
David Abel is a Senior Research Scientist at DeepMind on the Agency team, and an Honorary Fellow at the University of Edinburgh. His research blends computer science and philosophy, exploring foundational questions about reinforcement learning, definitions, and the nature of agency. Featured References Plasticity as the Mirror of Empowerment David Abel, Michael Bowling, André Barreto,
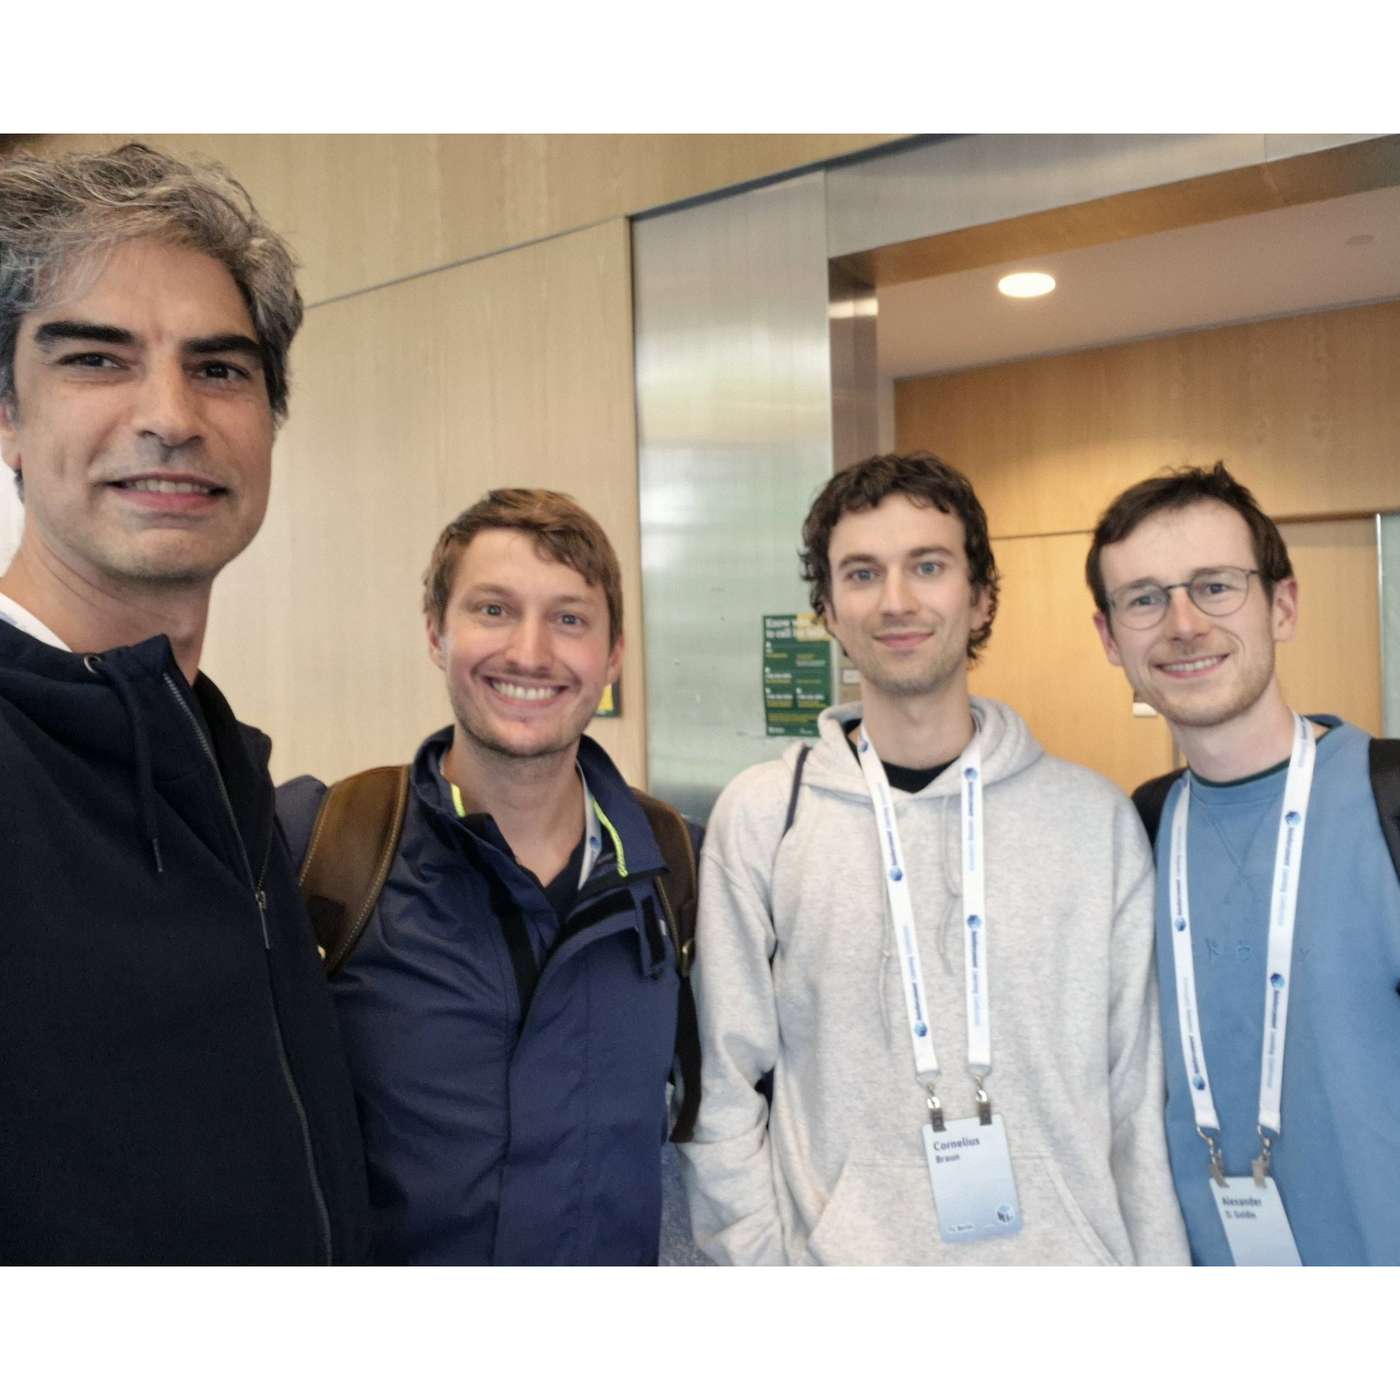
Jake Beck, Alex Goldie, & Cornelius Braun on Sutton's OaK, Metalearning, LLMs, Squirrels @ RLC 2025
Recorded at Reinforcement Learning Conference 2025 at University of Alberta, Edmonton Alberta Canada.Featured ReferencesLecture on the Oak Architecture, Rich SuttonAlberta Plan, Rich Sutton with Mike Bowling and Patrick Pilarski Additional ReferencesJacob Beck on Google Scholar Alex Goldie on Google ScholarCornelius Braun on Google ScholarReinforcement Learning Conference
Outstanding Paper Award Winners - 2/2 @ RLC 2025
We caught up with the RLC Outstanding Paper award winners for your listening pleasure. Recorded on location at Reinforcement Learning Conference 2025, at University of Alberta, in Edmonton Alberta Canada in August 2025.Featured References Empirical Reinforcement Learning ResearchMitigating Suboptimality of Deterministic Policy Gradients in Complex Q-functionsAyush Jain, Norio Kosaka, Xinh
Outstanding Paper Award Winners - 1/2 @ RLC 2025
We caught up with the RLC Outstanding Paper award winners for your listening pleasure. Recorded on location at Reinforcement Learning Conference 2025, at University of Alberta, in Edmonton Alberta Canada in August 2025.Featured References Scientific Understanding in Reinforcement Learning How Should We Meta-Learn Reinforcement Learning Algorithms? Alexander David Goldie, Zilin Wang, J
Thomas Akam on Model-based RL in the Brain
Prof Thomas Akam is a Neuroscientist at the Oxford University Department of Experimental Psychology. He is a Wellcome Career Development Fellow and Associate Professor at the University of Oxford, and leads the Cognitive Circuits research group.Featured ReferencesBrain Architecture for Adaptive BehaviourThomas Akam, RLDM 2025 TutorialAdditional ReferencesThomas Akam on Google ScholarpyPh
Stefano Albrecht on Multi-Agent RL @ RLDM 2025
Stefano V. Albrecht was previously Associate Professor at the University of Edinburgh, and is currently serving as Director of AI at startup Deepflow. He is a Program Chair of RLDM 2025 and is co-author of the MIT Press textbook "Multi-Agent Reinforcement Learning: Foundations and Modern Approaches".Featured ReferencesMulti-Agent Reinforcement Learning: Foundations and Modern ApproachesSt

Satinder Singh: The Origin Story of RLDM @ RLDM 2025
Professor Satinder Singh of Google DeepMind and U of Michigan is co-founder of RLDM. Here he narrates the origin story of the Reinforcement Learning and Decision Making meeting (not conference).Recorded on location at Trinity College Dublin, Ireland during RLDM 2025.Featured ReferencesRLDM 2025: Multi-disciplinary Conference on Reinforcement Learning and Decision Making (RLDM)June 11-14,
NeurIPS 2024 - Posters and Hallways 3
Posters and Hallway episodes are short interviews and poster summaries. Recorded at NeurIPS 2024 in Vancouver BC Canada. Featuring Claire Bizon Monroc from Inria: WFCRL: A Multi-Agent Reinforcement Learning Benchmark for Wind Farm Control Andrew Wagenmaker from UC Berkeley: Overcoming the Sim-to-Real Gap: Leveraging Simulation to Learn to Explore for Real-World RL Harley Wiltzer fro
NeurIPS 2024 - Posters and Hallways 2
Posters and Hallway episodes are short interviews and poster summaries. Recorded at NeurIPS 2024 in Vancouver BC Canada. Featuring Jonathan Cook from University of Oxford: Artificial Generational Intelligence: Cultural Accumulation in Reinforcement Learning Yifei Zhou from Berkeley AI Research: DigiRL: Training In-The-Wild Device-Control Agents with Autonomous Reinforcement Learning
NeurIPS 2024 - Posters and Hallways 1
Posters and Hallway episodes are short interviews and poster summaries. Recorded at NeurIPS 2024 in Vancouver BC Canada. Featuring Jiaheng Hu of University of Texas: Disentangled Unsupervised Skill Discovery for Efficient Hierarchical Reinforcement Learning Skander Moalla of EPFL: No Representation, No Trust: Connecting Representation, Collapse, and Trust Issues in PPO Adil Zouitine
Abhishek Naik on Continuing RL & Average Reward
Abhishek Naik was a student at University of Alberta and Alberta Machine Intelligence Institute, and he just finished his PhD in reinforcement learning, working with Rich Sutton. Now he is a postdoc fellow at the National Research Council of Canada, where he does AI research on Space applications. Featured References Reinforcement Learning for Continuing Problems Using Average Reward A
Neurips 2024 RL meetup Hot takes: What sucks about RL?
What do RL researchers complain about after hours at the bar? In this "Hot takes" episode, we find out! Recorded at The Pearl in downtown Vancouver, during the RL meetup after a day of Neurips 2024. Special thanks to "David Beckham" for the inspiration :)
RLC 2024 - Posters and Hallways 5
Posters and Hallway episodes are short interviews and poster summaries. Recorded at RLC 2024 in Amherst MA. Featuring: 0:01 David Radke of the Chicago Blackhawks NHL on RL for professional sports 0:56 Abhishek Naik from the National Research Council on Continuing RL and Average Reward 2:42 Daphne Cornelisse from NYU on Autonomous Driving and Multi-Agent RL 08:58 Shray Bansal from G
RLC 2024 - Posters and Hallways 4
Posters and Hallway episodes are short interviews and poster summaries. Recorded at RLC 2024 in Amherst MA. Featuring: 0:01 David Abel from DeepMind on 3 Dogmas of RL 0:55 Kevin Wang from Brown on learning variable depth search for MCTS 2:17 Ashwin Kumar from Washington University in St Louis on fairness in resource allocation 3:36 Prabhat Nagarajan from UAlberta on Value overesti
RLC 2024 - Posters and Hallways 3
Posters and Hallway episodes are short interviews and poster summaries. Recorded at RLC 2024 in Amherst MA. Featuring: 0:01 Kris De Asis from Openmind on Time Discretization 2:23 Anna Hakhverdyan from U of Alberta on Online Hyperparameters 3:59 Dilip Arumugam from Princeton on Information Theory and Exploration 5:04 Micah Carroll from UC Berkeley on Changing preferences and AI align
RLC 2024 - Posters and Hallways 2
Posters and Hallway episodes are short interviews and poster summaries. Recorded at RLC 2024 in Amherst MA. Featuring: 0:01 Hector Kohler from Centre Inria de l'Université de Lille with "Interpretable and Editable Programmatic Tree Policies for Reinforcement Learning" 2:29 Quentin Delfosse from TU Darmstadt on "Interpretable Concept Bottlenecks to Align Reinforcement Learning Agents"
RLC 2024 - Posters and Hallways 1
Posters and Hallway episodes are short interviews and poster summaries. Recorded at RLC 2024 in Amherst MA. Featuring: 0:01 Ann Huang from Harvard on Learning Dynamics and the Geometry of Neural Dynamics in Recurrent Neural Controllers 1:37 Jannis Blüml from TU Darmstadt on HackAtari: Atari Learning Environments for Robust and Continual Reinforcement Learning 3:13 Benjamin Fuhrer fro
Finale Doshi-Velez on RL for Healthcare @ RCL 2024
Finale Doshi-Velez is a Professor at the Harvard Paulson School of Engineering and Applied Sciences. This off-the-cuff interview was recorded at UMass Amherst during the workshop day of RL Conference on August 9th 2024. Host notes: I've been a fan of some of Prof Doshi-Velez' past work on clinical RL and hoped to feature her for some time now, so I jumped at the chance to get a few min
David Silver 2 - Discussion after Keynote @ RCL 2024
Thanks to Professor Silver for permission to record this discussion after his RLC 2024 keynote lecture. Recorded at UMass Amherst during RCL 2024.Due to the live recording environment, audio quality varies. We publish this audio in its raw form to preserve the authenticity and immediacy of the discussion. References AlphaProof announcement on DeepMind's blogDiscovering Reinforcement
David Silver @ RCL 2024
David Silver is a principal research scientist at DeepMind and a professor at University College London. This interview was recorded at UMass Amherst during RLC 2024. References Discovering Reinforcement Learning Algorithms, Oh et al -- His keynote at RLC 2024 referred to more recent update to this work, yet to be published Mastering Chess and Shogi by Self-Play with a General Reinf
Vincent Moens on TorchRL
Dr. Vincent Moens is an Applied Machine Learning Research Scientist at Meta, and an author of TorchRL and TensorDict in pytorch. Featured References TorchRL: A data-driven decision-making library for PyTorch Albert Bou, Matteo Bettini, Sebastian Dittert, Vikash Kumar, Shagun Sodhani, Xiaomeng Yang, Gianni De Fabritiis, Vincent Moens Additional References TorchRL on github TensorDict D
Arash Ahmadian on Rethinking RLHF
Arash Ahmadian is a Researcher at Cohere and Cohere For AI focussed on Preference Training of large language models. He’s also a researcher at the Vector Institute of AI.Featured ReferenceBack to Basics: Revisiting REINFORCE Style Optimization for Learning from Human Feedback in LLMsArash Ahmadian, Chris Cremer, Matthias Gallé, Marzieh Fadaee, Julia Kreutzer, Olivier Pietquin, Ahmet Üstün
Glen Berseth on RL Conference
Glen Berseth is an assistant professor at the Université de Montréal, a core academic member of the Mila - Quebec AI Institute, a Canada CIFAR AI chair, member l'Institute Courtios, and co-director of the Robotics and Embodied AI Lab (REAL). Featured Links Reinforcement Learning Conference Closing the Gap between TD Learning and Supervised Learning--A Generalisation Point of View Raj G
Ian Osband
Ian Osband is a Research scientist at OpenAI (ex DeepMind, Stanford) working on decision making under uncertainty. We spoke about: - Information theory and RL - Exploration, epistemic uncertainty and joint predictions - Epistemic Neural Networks and scaling to LLMs Featured References Reinforcement Learning, Bit by Bit Xiuyuan Lu, Benjamin Van Roy, Vikranth Dwaracherla, Morteza Ibrahim

Sharath Chandra Raparthy
Sharath Chandra Raparthy on In-Context Learning for Sequential Decision Tasks, GFlowNets, and more! Sharath Chandra Raparthy is an AI Resident at FAIR at Meta, and did his Master's at Mila. Featured Reference Generalization to New Sequential Decision Making Tasks with In-Context Learning Sharath Chandra Raparthy , Eric Hambro, Robert Kirk , Mikael Henaff, , Roberta Raileanu Additio

Pierluca D'Oro and Martin Klissarov
Pierluca D'Oro and Martin Klissarov on Motif and RLAIF, Noisy Neighborhoods and Return Landscapes, and more! Pierluca D'Oro is PhD student at Mila and visiting researcher at Meta.Martin Klissarov is a PhD student at Mila and McGill and research scientist intern at Meta. Featured References Motif: Intrinsic Motivation from Artificial Intelligence Feedback Martin Klissarov*, Pierluca D'

Martin Riedmiller
Martin Riedmiller of Google DeepMind on controlling nuclear fusion plasma in a tokamak with RL, the original Deep Q-Network, Neural Fitted Q-Iteration, Collect and Infer, AGI for control systems, and tons more! Martin Riedmiller is a research scientist and team lead at DeepMind. Featured References Magnetic control of tokamak plasmas through deep reinforcement learning Jonas Degrave
Max Schwarzer
Max Schwarzer is a PhD student at Mila, with Aaron Courville and Marc Bellemare, interested in RL scaling, representation learning for RL, and RL for science. Max spent the last 1.5 years at Google Brain/DeepMind, and is now at Apple Machine Learning Research. Featured References Bigger, Better, Faster: Human-level Atari with human-level efficiency Max Schwarzer, Johan Obando-Ceron, A

Julian Togelius
Julian Togelius is an Associate Professor of Computer Science and Engineering at NYU, and Cofounder and research director at modl.ai Featured References Choose Your Weapon: Survival Strategies for Depressed AI AcademicsJulian Togelius, Georgios N. YannakakisLearning Controllable 3D Level GeneratorsZehua Jiang, Sam Earle, Michael Cerny Green, Julian TogeliusPCGRL: Procedural Content Gene

Jakob Foerster
Jakob Foerster on Multi-Agent learning, Cooperation vs Competition, Emergent Communication, Zero-shot coordination, Opponent Shaping, agents for Hanabi and Prisoner's Dilemma, and more. Jakob Foerster is an Associate Professor at University of Oxford. Featured References Learning with Opponent-Learning Awareness Jakob N. Foerster, Richard Y. Chen, Maruan Al-Shedivat, Shimon Whiteson, P

Danijar Hafner 2
Danijar Hafner on the DreamerV3 agent and world models, the Director agent and heirarchical RL, realtime RL on robots with DayDreamer, and his framework for unsupervised agent design! Danijar Hafner is a PhD candidate at the University of Toronto with Jimmy Ba, a visiting student at UC Berkeley with Pieter Abbeel, and an intern at DeepMind. He has been our guest before back on episode 1

Jeff Clune
AI Generating Algos, Learning to play Minecraft with Video PreTraining (VPT), Go-Explore for hard exploration, POET and Open Endedness, AI-GAs and ChatGPT, AGI predictions, and lots more! Professor Jeff Clune is Associate Professor of Computer Science at University of British Columbia, a Canada CIFAR AI Chair and Faculty Member at Vector Institute, and Senior Research Advisor at DeepMind
Natasha Jaques 2
Hear about why OpenAI cites her work in RLHF and dialog models, approaches to rewards in RLHF, ChatGPT, Industry vs Academia, PsiPhi-Learning, AGI and more! Dr Natasha Jaques is a Senior Research Scientist at Google Brain. Featured References Way Off-Policy Batch Deep Reinforcement Learning of Implicit Human Preferences in Dialog Natasha Jaques, Asma Ghandeharioun, Judy Hanwen Shen, Crai

Jacob Beck and Risto Vuorio
Jacob Beck and Risto Vuorio on their recent Survey of Meta-Reinforcement Learning. Jacob and Risto are Ph.D. students at Whiteson Research Lab at University of Oxford. Featured Reference A Survey of Meta-Reinforcement LearningJacob Beck, Risto Vuorio, Evan Zheran Liu, Zheng Xiong, Luisa Zintgraf, Chelsea Finn, Shimon Whiteson Additional References VariBAD: A Very Good Method for
John Schulman
John Schulman is a cofounder of OpenAI, and currently a researcher and engineer at OpenAI.Featured ReferencesWebGPT: Browser-assisted question-answering with human feedbackReiichiro Nakano, Jacob Hilton, Suchir Balaji, Jeff Wu, Long Ouyang, Christina Kim, Christopher Hesse, Shantanu Jain, Vineet Kosaraju, William Saunders, Xu Jiang, Karl Cobbe, Tyna Eloundou, Gretchen Krueger, Kevin Butto

Sven Mika
Sven Mika is the Reinforcement Learning Team Lead at Anyscale, and lead committer of RLlib. He holds a PhD in biomathematics, bioinformatics, and computational biology from Witten/Herdecke University. Featured ReferencesRLlib Documentation: RLlib: Industry-Grade Reinforcement LearningRay: DocumentationRLlib: Abstractions for Distributed Reinforcement LearningEric Liang, Richard Liaw, Phil
Karol Hausman and Fei Xia
Karol Hausman is a Senior Research Scientist at Google Brain and an Adjunct Professor at Stanford working on robotics and machine learning. Karol is interested in enabling robots to acquire general-purpose skills with minimal supervision in real-world environments. Fei Xia is a Research Scientist with Google Research. Fei Xia is mostly interested in robot learning in complex and unstructu

Sai Krishna Gottipati
Saikrishna Gottipati is an RL Researcher at AI Redefined, working on RL, MARL, human in the loop learning.Featured ReferencesCogment: Open Source Framework For Distributed Multi-actor Training, Deployment & OperationsAI Redefined, Sai Krishna Gottipati, Sagar Kurandwad, Clodéric Mars, Gregory Szriftgiser, François ChabotDo As You Teach: A Multi-Teacher Approach to Self-Play in Deep Re

Aravind Srinivas 2
Aravind Srinivas is back! He is now a research Scientist at OpenAI.Featured ReferencesDecision Transformer: Reinforcement Learning via Sequence ModelingLili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor MordatchVideoGPT: Video Generation using VQ-VAE and TransformersWilson Yan, Yunzhi Zhang, Pieter Abbeel, Aravind Srin
Rohin Shah
Dr. Rohin Shah is a Research Scientist at DeepMind, and the editor and main contributor of the Alignment Newsletter.Featured ReferencesThe MineRL BASALT Competition on Learning from Human FeedbackRohin Shah, Cody Wild, Steven H. Wang, Neel Alex, Brandon Houghton, William Guss, Sharada Mohanty, Anssi Kanervisto, Stephanie Milani, Nicholay Topin, Pieter Abbeel, Stuart Russell, Anca DraganPr

Robert Lange
Robert Tjarko Lange is a PhD student working at the Technical University Berlin.Featured ReferencesLearning not to learn: Nature versus nurture in silicoLange, R. T., & Sprekeler, H. (2020)On Lottery Tickets and Minimal Task Representations in Deep Reinforcement LearningVischer, M. A., Lange, R. T., & Sprekeler, H. (2021). Semantic RL with Action Grammars: Data-Efficient Learning

NeurIPS 2021 Political Economy of Reinforcement Learning Systems (PERLS) Workshop
We hear about the idea of PERLS and why its important to talk about.Political Economy of Reinforcement Learning (PERLS) Workshop at NeurIPS 2021 on Tues Dec 14th NeurIPS 2021

Amy Zhang
Amy Zhang is a postdoctoral scholar at UC Berkeley and a research scientist at Facebook AI Research. She will be starting as an assistant professor at UT Austin in Spring 2023. Featured References Invariant Causal Prediction for Block MDPs Amy Zhang, Clare Lyle, Shagun Sodhani, Angelos Filos, Marta Kwiatkowska, Joelle Pineau, Yarin Gal, Doina Precup Multi-Task Reinforcement Learning with

Xianyuan Zhan
Xianyuan Zhan is currently a research assistant professor at the Institute for AI Industry Research (AIR), Tsinghua University. He received his Ph.D. degree at Purdue University. Before joining Tsinghua University, Dr. Zhan worked as a researcher at Microsoft Research Asia (MSRA) and a data scientist at JD Technology. At JD Technology, he led the research that uses offline RL to optimiz
Eugene Vinitsky
Eugene Vinitsky is a PhD student at UC Berkeley advised by Alexandre Bayen. He has interned at Tesla and Deepmind. Featured References A learning agent that acquires social norms from public sanctions in decentralized multi-agent settings Eugene Vinitsky, Raphael Köster, John P. Agapiou, Edgar Duéñez-Guzmán, Alexander Sasha Vezhnevets, Joel Z. Leibo Optimizing Mixed Autonomy Traffic Flow
Jess Whittlestone
Dr. Jess Whittlestone is a Senior Research Fellow at the Centre for the Study of Existential Risk and the Leverhulme Centre for the Future of Intelligence, both at the University of Cambridge. Featured References The Societal Implications of Deep Reinforcement Learning Jess Whittlestone, Kai Arulkumaran, Matthew Crosby Artificial Canaries: Early Warning Signs for Anticipatory and Democrat
Aleksandra Faust
Dr Aleksandra Faust is a Staff Research Scientist and Reinforcement Learning research team co-founder at Google Brain Research. Featured References Reinforcement Learning and Planning for Preference Balancing Tasks Faust 2014 Learning Navigation Behaviors End-to-End with AutoRL Hao-Tien Lewis Chiang, Aleksandra Faust, Marek Fiser, Anthony Francis Evolving Rewards to Automate Reinforcement
Sam Ritter
Sam Ritter is a Research Scientist on the neuroscience team at DeepMind. Featured References Unsupervised Predictive Memory in a Goal-Directed Agent (MERLIN) Greg Wayne, Chia-Chun Hung, David Amos, Mehdi Mirza, Arun Ahuja, Agnieszka Grabska-Barwinska, Jack Rae, Piotr Mirowski, Joel Z. Leibo, Adam Santoro, Mevlana Gemici, Malcolm Reynolds, Tim Harley, Josh Abramson, Shakir Mohamed, Danilo
Thomas Krendl Gilbert
Thomas Krendl Gilbert is a PhD student at UC Berkeley’s Center for Human-Compatible AI, specializing in Machine Ethics and Epistemology. Featured References Hard Choices in Artificial Intelligence: Addressing Normative Uncertainty through Sociotechnical Commitments Roel Dobbe, Thomas Krendl Gilbert, Yonatan Mintz Mapping the Political Economy of Reinforcement Learning Systems: The Case of
Marc G. Bellemare
Professor Marc G. Bellemare is a Research Scientist at Google Research (Brain team), An Adjunct Professor at McGill University, and a Canada CIFAR AI Chair. Featured References The Arcade Learning Environment: An Evaluation Platform for General Agents Marc G. Bellemare, Yavar Naddaf, Joel Veness, Michael Bowling Human-level control through deep reinforcement learning Volodymyr Mnih, Koray
Robert Osazuwa Ness
Robert Osazuwa Ness is an adjunct professor of computer science at Northeastern University, an ML Research Engineer at Gamalon, and the founder of AltDeep School of AI. He holds a PhD in statistics. He studied at Johns Hopkins SAIS and then Purdue University. References Altdeep School of AI, Altdeep on Twitch, Substack, Robert Ness Altdeep Causal Generative Machine Learning Minicourse,
Marlos C. Machado
Dr. Marlos C. Machado is a research scientist at DeepMind and an adjunct professor at the University of Alberta. He holds a PhD from the University of Alberta and a MSc and BSc from UFMG, in Brazil. Featured References Revisiting the Arcade Learning Environment: Evaluation Protocols and Open Problems for General Agents Marlos C. Machado, Marc G. Bellemare, Erik Talvitie, Joel Veness, Matt
Nathan Lambert
Nathan Lambert is a PhD Candidate at UC Berkeley. Featured References Learning Accurate Long-term Dynamics for Model-based Reinforcement Learning Nathan O. Lambert, Albert Wilcox, Howard Zhang, Kristofer S. J. Pister, Roberto Calandra Objective Mismatch in Model-based Reinforcement Learning Nathan Lambert, Brandon Amos, Omry Yadan, Roberto Calandra Low Level Control of a Quadrotor with De
Kai Arulkumaran
Kai Arulkumaran is a researcher at Araya in Tokyo. Featured References AlphaStar: An Evolutionary Computation Perspective Kai Arulkumaran, Antoine Cully, Julian Togelius Analysing Deep Reinforcement Learning Agents Trained with Domain Randomisation Tianhong Dai, Kai Arulkumaran, Tamara Gerbert, Samyakh Tukra, Feryal Behbahani, Anil Anthony Bharath Training Agents using Upside-Down Reinfor
Michael Dennis
Michael Dennis is a PhD student at the Center for Human-Compatible AI at UC Berkeley, supervised by Professor Stuart Russell. I'm interested in robustness in RL and multi-agent RL, specifically as it applies to making the interaction between AI systems and society at large to be more beneficial. --Michael Dennis Featured References Emergent Complexity and Zero-shot Transfer via Unsuperv
Roman Ring
Roman Ring is a Research Engineer at DeepMind. Featured References Grandmaster level in StarCraft II using multi-agent reinforcement learning Vinyals et al, 2019 Replicating DeepMind StarCraft II Reinforcement Learning Benchmark with Actor-Critic Methods Roman Ring, 2018 Additional References Relational Deep Reinforcement Learning, Zambaldi et al 2018 StarCraft II: A New Challenge for Re
Shimon Whiteson
Shimon Whiteson is a Professor of Computer Science at Oxford University, the head of WhiRL, the Whiteson Research Lab at Oxford, and Head of Research at Waymo UK. Featured References VariBAD: A Very Good Method for Bayes-Adaptive Deep RL via Meta-Learning Luisa Zintgraf, Kyriacos Shiarlis, Maximilian Igl, Sebastian Schulze, Yarin Gal, Katja Hofmann, Shimon Whiteson Monotonic Value Functio
Aravind Srinivas
Aravind Srinivas is a 3rd year PhD student at UC Berkeley advised by Prof. Abbeel. He co-created and co-taught a grad course on Deep Unsupervised Learning at Berkeley. Featured References Data-Efficient Image Recognition with Contrastive Predictive Coding Olivier J. Hénaff, Aravind Srinivas, Jeffrey De Fauw, Ali Razavi, Carl Doersch, S. M. Ali Eslami, Aaron van den Oord Contrastive Unsupe
Taylor Killian
Taylor Killian is a Ph.D. student at the University of Toronto and the Vector Institute, and an Intern at Google Brain. Featured References Direct Policy Transfer with Hidden Parameter Markov Decision Processes Yao, Killian, Konidaris, Doshi-Velez Robust and Efficient Transfer Learning with Hidden Parameter Markov Decision Processes Killian, Daulton, Konidaris, Doshi-Velez Transfer Learni
Nan Jiang
Nan Jiang is an Assistant Professor of Computer Science at University of Illinois. He was a Postdoc Microsoft Research, and did his PhD at University of Michigan under Professor Satinder Singh. Featured References Reinforcement Learning: Theory and Algorithms Alekh Agarwal Nan Jiang Sham M. Kakade Model-based RL in Contextual Decision Processes: PAC bounds and Exponential Improvements ov
Danijar Hafner
Danijar Hafner is a PhD student at the University of Toronto, and a student researcher at Google Research, Brain Team and the Vector Institute. He holds a Masters of Research from University College London. Featured References A deep learning framework for neuroscience Blake A. Richards, Timothy P. Lillicrap , Philippe Beaudoin, Yoshua Bengio, Rafal Bogacz, Amelia Christensen, Claudia Cl
Csaba Szepesvari
Csaba Szepesvari is: Head of the Foundations Team at DeepMind Professor of Computer Science at the University of Alberta Canada CIFAR AI Chair Fellow at the Alberta Machine Intelligence Institute Co-Author of the book Bandit Algorithms along with Tor Lattimore, and author of the book Algorithms for Reinforcement Learning References Bandit based monte-carlo planning, Levente Kocsis, Csaba
Ben Eysenbach
Ben Eysenbach is a PhD student in the Machine Learning Department at Carnegie Mellon University. He was a Resident at Google Brain, and studied math and computer science at MIT. He co-founded the ICML Exploration in Reinforcement Learning workshop. Featured References Diversity is All You Need: Learning Skills without a Reward Function Benjamin Eysenbach, Abhishek Gupta, Julian Ibarz, S
NeurIPS 2019 Deep RL Workshop
Thank you to all the presenters that participated. I covered as many as I could given the time and crowds, if you were not included and wish to be, please email talkrl@pathwayi.com More details on the official NeurIPS Deep RL Workshop site. 0:23 Approximating two value functions instead of one: towards characterizing a new family of Deep Reinforcement Learning algorithms; Matthia Sabate
Scott Fujimoto
Scott Fujimoto is a PhD student at McGill University and Mila. He is the author of TD3 as well as some of the recent developments in batch deep reinforcement learning. Featured References Addressing Function Approximation Error in Actor-Critic Methods Scott Fujimoto, Herke van Hoof, David Meger Off-Policy Deep Reinforcement Learning without Exploration Scott Fujimoto, David Meger, Doina
Jessica Hamrick
Dr. Jessica Hamrick is a Research Scientist at DeepMind. She holds a PhD in Psychology from UC Berkeley. Featured References Structured agents for physical construction Victor Bapst, Alvaro Sanchez-Gonzalez, Carl Doersch, Kimberly L. Stachenfeld, Pushmeet Kohli, Peter W. Battaglia, Jessica B. Hamrick Analogues of mental simulation and imagination in deep learning Jessica Hamrick Additiona
Pablo Samuel Castro
Dr Pablo Samuel Castro is a Staff Research Software Engineer at Google Brain. He is the main author of the Dopamine RL framework. Featured References A Comparative Analysis of Expected and Distributional Reinforcement Learning Clare Lyle, Pablo Samuel Castro, Marc G. Bellemare A Geometric Perspective on Optimal Representations for Reinforcement Learning Marc G. Bellemare, Will Dabney, R
Kamyar Azizzadenesheli
Dr. Kamyar Azizzadenesheli is a post-doctorate scholar at Caltech. His research interest is mainly in the area of Machine Learning, from theory to practice, with the main focus in Reinforcement Learning. He will be joining Purdue University as an Assistant CS Professor in Fall 2020. Featured References Efficient Exploration through Bayesian Deep Q-Networks Kamyar Azizzadenesheli, Animas
Antonin Raffin and Ashley Hill
Antonin Raffin is a researcher at the German Aerospace Center (DLR) in Munich, working in the Institute of Robotics and Mechatronics. His research is on using machine learning for controlling real robots (because simulation is not enough), with a particular interest for reinforcement learning. Ashley Hill is doing his thesis on improving control algorithms using machine learning for real
Michael Littman
Michael L Littman is a professor of Computer Science at Brown University. He was elected ACM Fellow in 2018 "For contributions to the design and analysis of sequential decision making algorithms in artificial intelligence". Featured References Convergent Actor Critic by Humans James MacGlashan, Michael L. Littman, David L. Roberts, Robert Tyler Loftin, Bei Peng, Matthew E. Taylor People
Natasha Jaques
Natasha Jaques is a PhD candidate at MIT working on affective and social intelligence. She has interned with DeepMind and Google Brain, and was an OpenAI Scholars mentor. Her paper “Social Influence as Intrinsic Motivation for Multi-Agent Deep Reinforcement Learning” received an honourable mention for best paper at ICML 2019. Featured References Social Influence as Intrinsic Motivation
About TalkRL Podcast: All Reinforcement Learning, All the Time
August 2, 2019 Transcript The idea with TalkRL Podcast is to hear from brilliant folks from across the world of Reinforcement Learning, both research and applications. As much as possible, I want to hear from them in their own language. I try to get to know as much as I can about their work before hand. And Im not here to convert anyone, I want to reach people who are already into RL.
Recommended
English Vocabulary Help

Talk About Talk - Executive & Leadership Communication Skills
Learn English B1 with Daily News | English Listening Practice

Stand In The Circle

English with Olivia | Slow Conversations & Vocabulary

This Past Weekend w/ Theo Von

Learn 50 English Phrases While You Sleep | Everyday English Phrases & Vocabulary

پلی لیست | PlayList

Conspiracy Files with Paige Carter
Learn English A2 with Daily News | Simple English Listening Practice

Bible Tea

Bad Friends
